Research Blogs
September 19, 2026
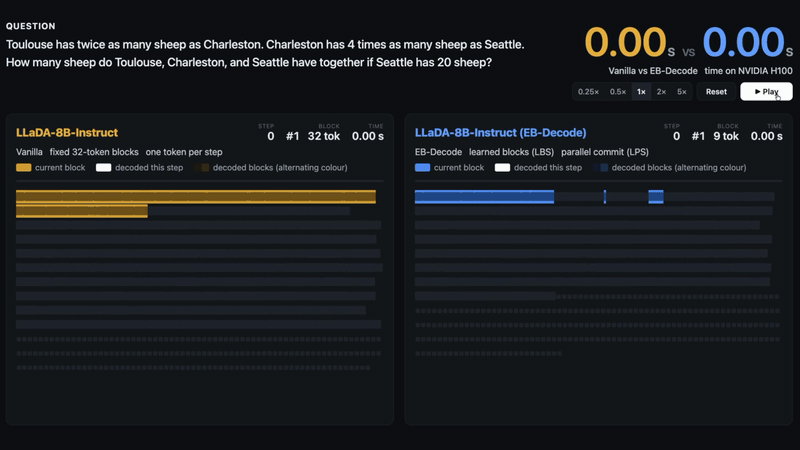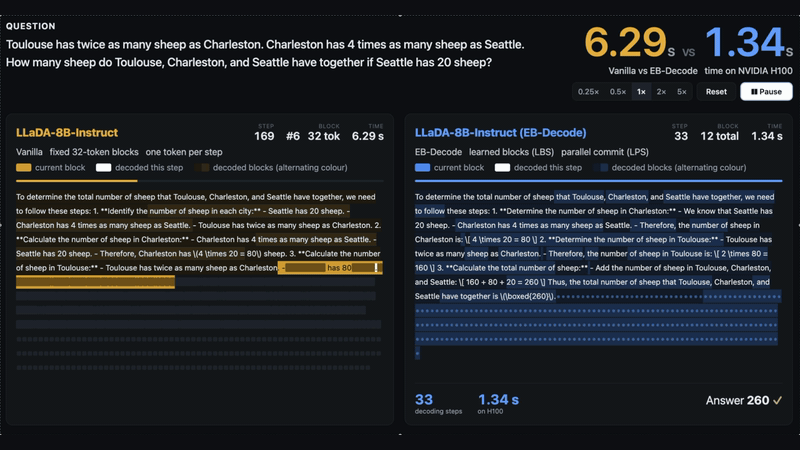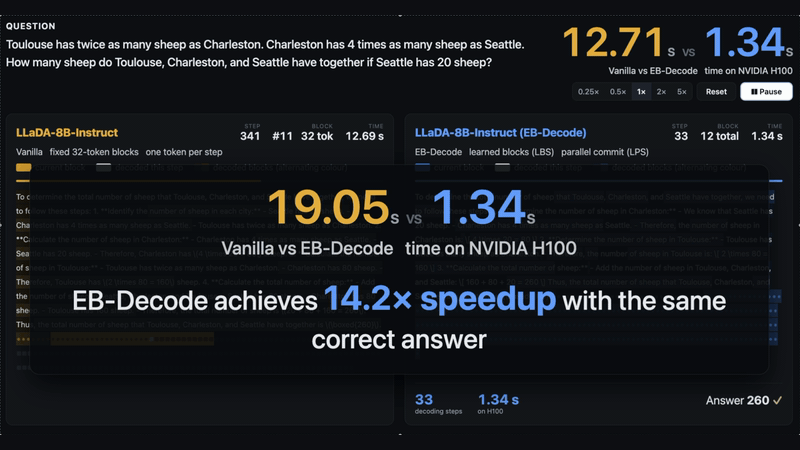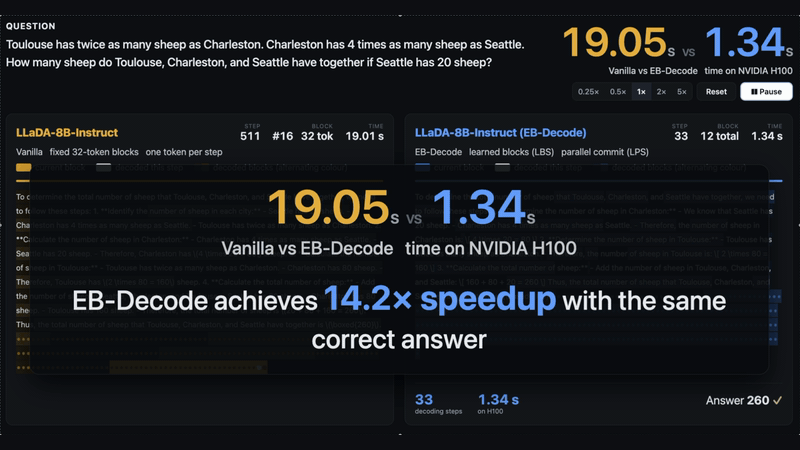
Two lightweight routers learn which tokens a diffusion LLM should decode together and which predictions can be finalized early. EB-Decode reaches 3.53-18.76x throughput, with the base model left frozen.

June 22, 2026
HiLo-Token allocates more tokens to high-frequency, context-rich regions and fewer tokens to low-frequency regions for DiT-based image editing, reducing serving costs by one-third without quality regression.
September 25, 2024
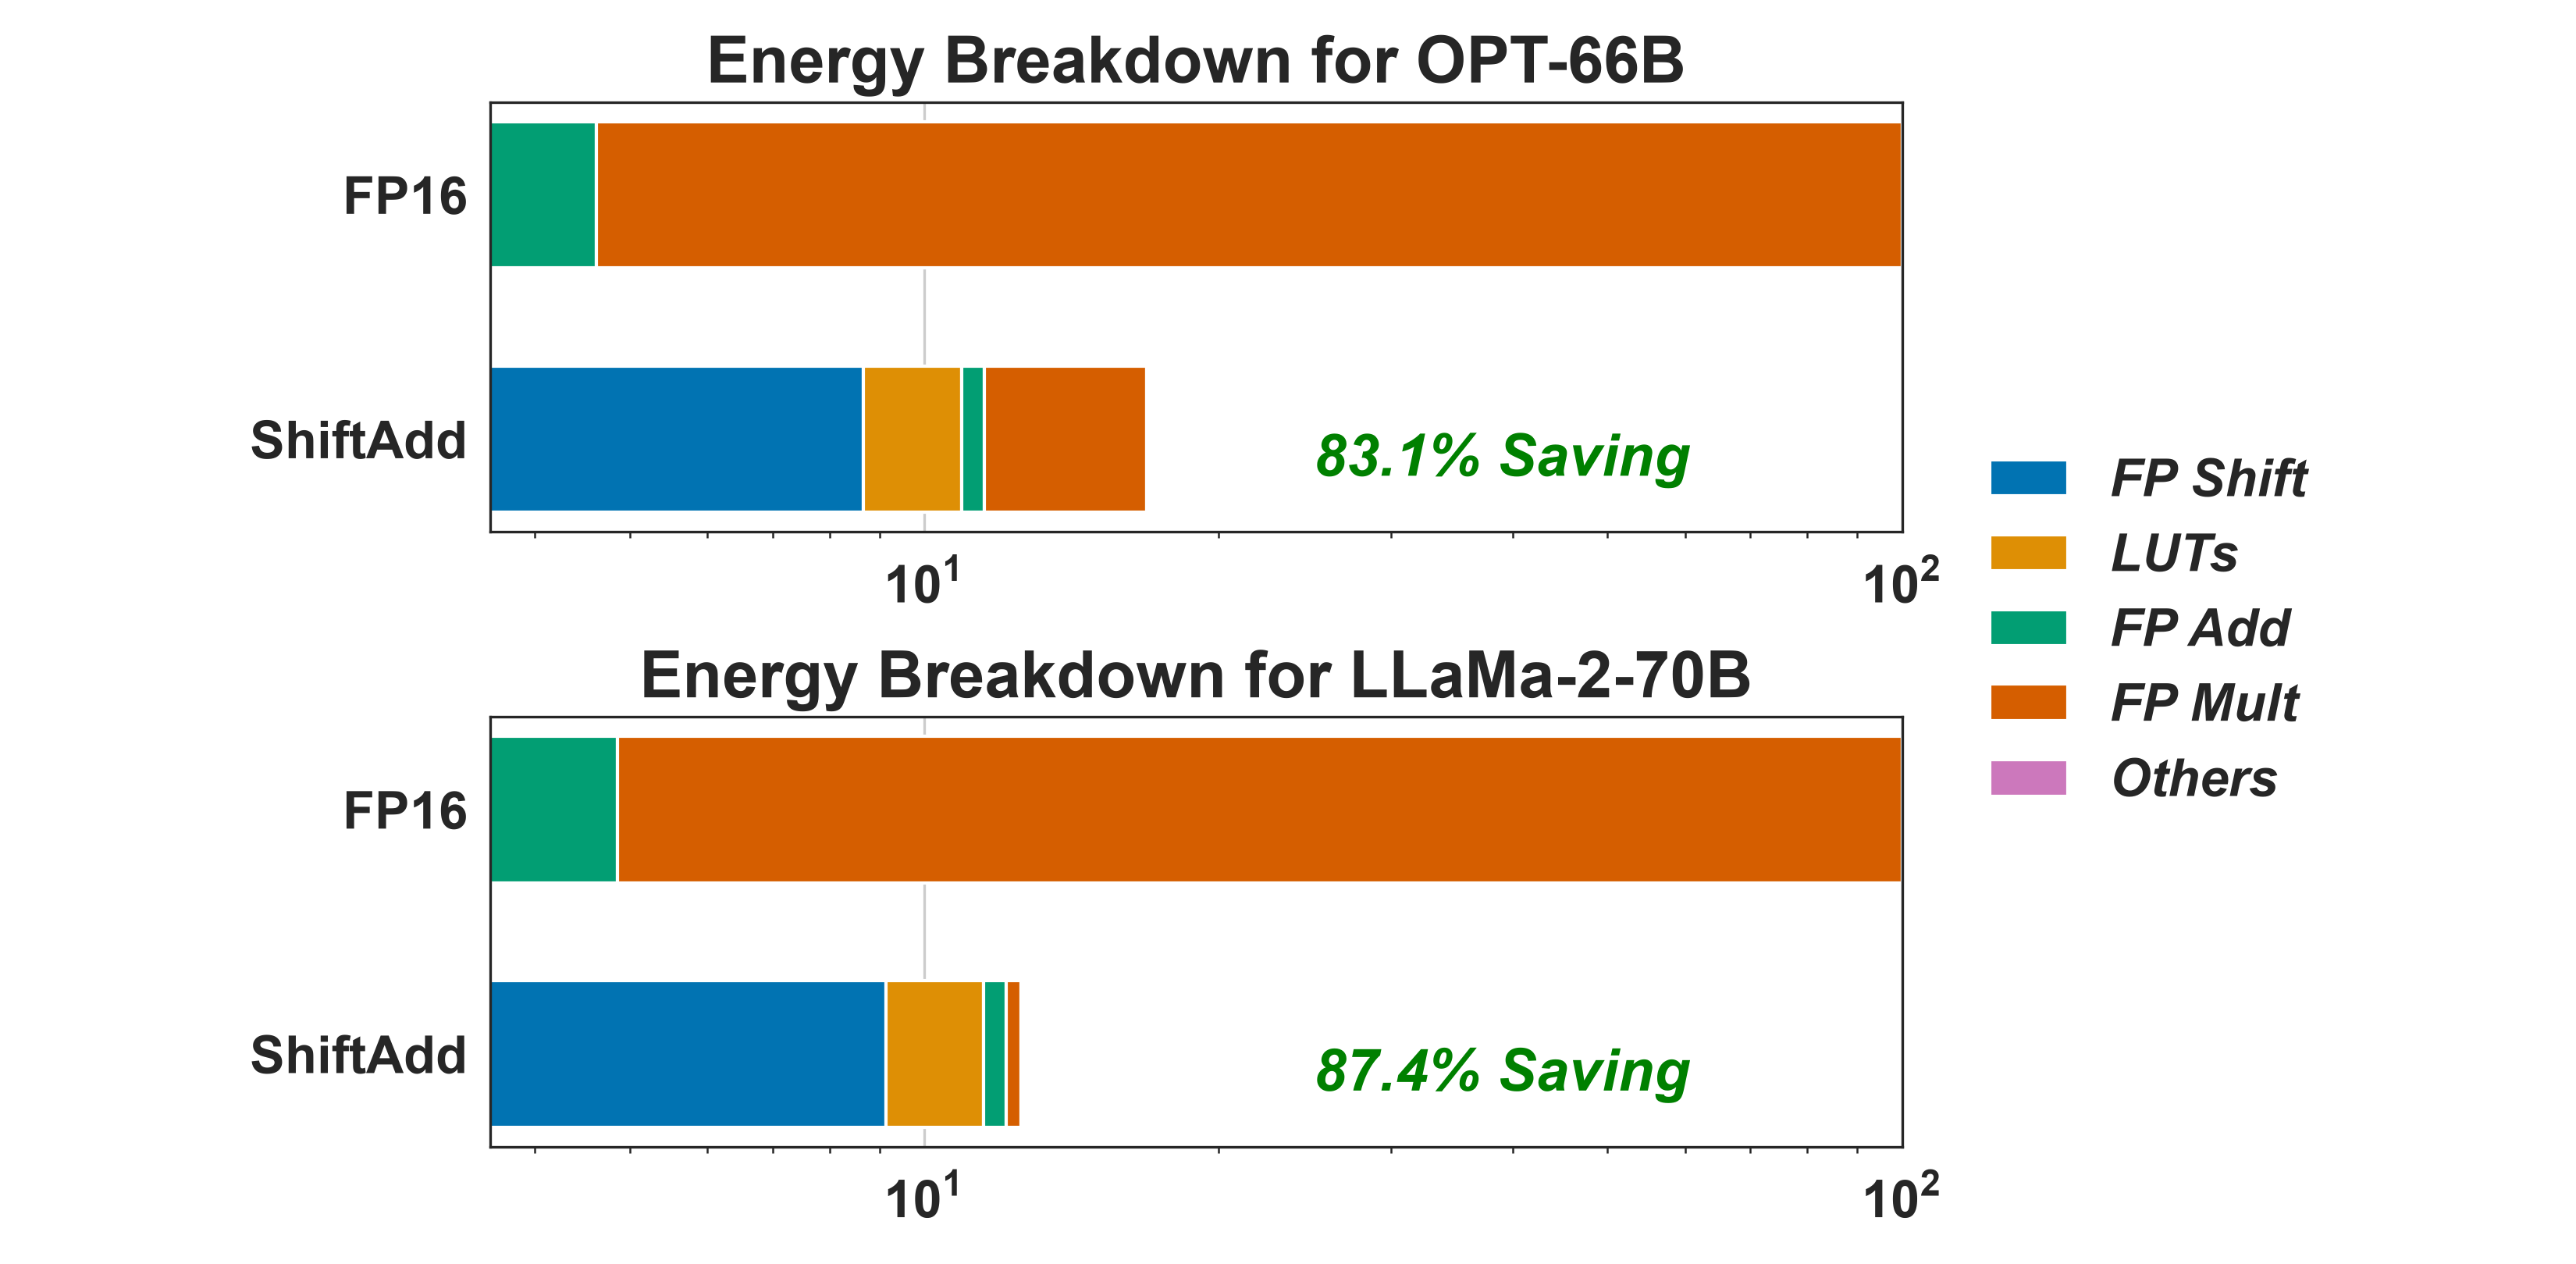
A series of hardware-inspired, multiplication-less networks-ShiftAddNet, ShiftAddViT, and ShiftAddLLM-that reparameterize CNNs, ViTs, and LLMs with bitwise shifts and adds for large energy and latency savings.
June 18, 2022
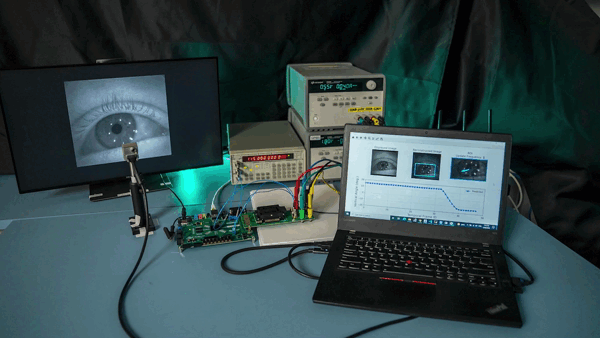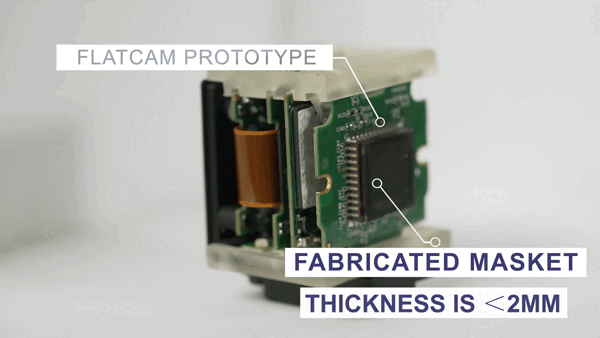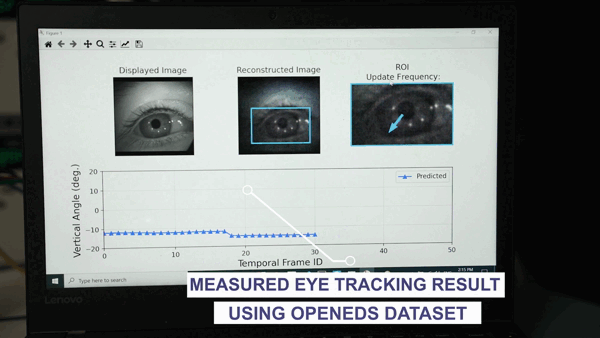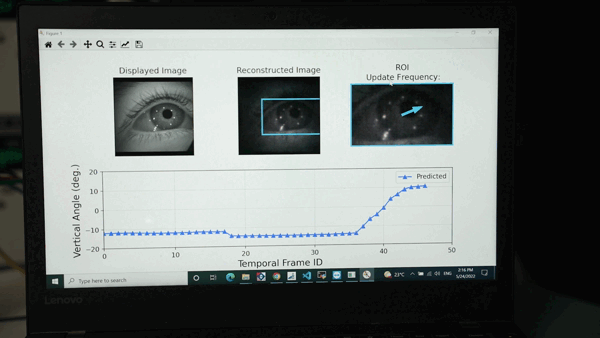
EyeCoD pairs lensless FlatCams with a predict-then-focus algorithm and a dedicated accelerator, achieving 10.95x, 3.21x, and 12.85x speedups over CPUs, GPUs, and a prior-art eye tracking processor.
October 2, 2020
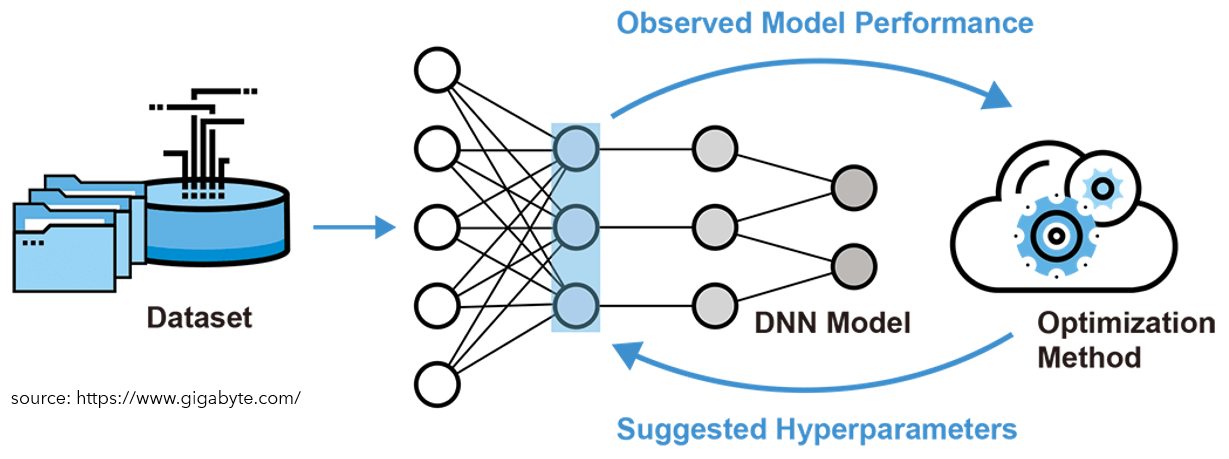
Summary of efficient DNN training methods including E²Train, EB Train, FracTrain, and ShiftAddNet. Achieving over 80% training energy cost savings through data-level, model-level, and algorithm-level optimizations.
March 21, 2020
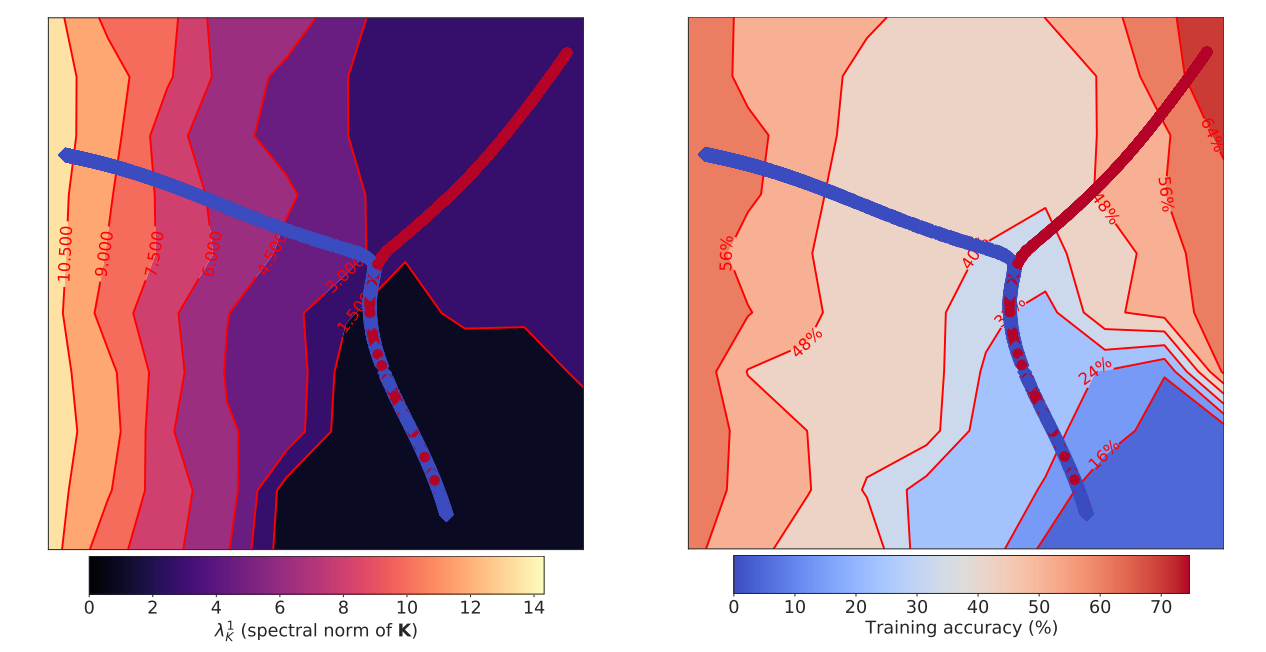
Recent works show that DNN training undergoes different stages, each stage shows different effects. Analysis from optimization, generalization, and frequency domain perspectives.